PostgreSQL Architecture Explained
On this page
Why does a crash in one session kick everyone off?
Sooner or later you'll see this in the log: one query hit a bug, and suddenly every connected application lost its session. It looks like overkill. Once you know how PostgreSQL is put together, it makes complete sense. This lesson explains the architecture you'll be tuning, backing up and debugging for the rest of the course.
One process per connection
When the server starts, one supervisor process begins listening on port 5432. It's called the postmaster. Each time a client connects, the postmaster forks a new operating system process just for that client. That backend process parses, plans and runs every statement the client sends until it disconnects.
You can see this for yourself. Open two psql sessions, then run this from a normal shell:
ps aux | grep postgresYou'll see one line per session, plus a handful of helpers with names like checkpointer, background writer and walwriter.
All backends share one block of memory, which you'll meet in a moment. That's the answer to the opening question. If one backend crashes, it might have left that shared memory half-written. The postmaster can't tell, so it stops every backend, replays the log to get back to a consistent state, and accepts connections again.
The process model has a cost too. A process is heavier than a thread, and each connection holds some memory even when idle. That's why busy systems put a connection pooler such as PgBouncer in front of PostgreSQL, so a few hundred real connections can serve thousands of clients.
Background processes: WAL writer, checkpointer and autovacuum
Besides the backends, a handful of background processes keep the cluster healthy. Each has one job:
- WAL writer flushes the write-ahead log (WAL) from memory to disk in the background, so commits have less left to do.
- Background writer writes changed pages from memory to the data files a little at a time, so backends rarely have to do it themselves.
- Checkpointer periodically writes every changed page to disk and records a checkpoint. After a crash, recovery only replays the log from the last checkpoint.
- Autovacuum launcher starts workers that clean up old row versions left behind by UPDATE and DELETE. Day 24 explains why those exist.
- Logging collector and archiver are optional. One writes server output to log files, the other copies finished log segments somewhere safe for point-in-time recovery.
Older material also lists a "stats collector" process. It was removed in PostgreSQL 15, and statistics now live in shared memory.
Memory settings: shared_buffers and work_mem
PostgreSQL memory comes in two kinds. Shared memory is allocated once at startup and used by every process. Local memory belongs to one backend. Four settings matter most:
| Setting | What it controls | What to watch for |
|---|---|---|
shared_buffers | The shared page cache. Every table read goes through it. | About 25% of RAM is a common starting point. Changing it needs a restart. |
work_mem | Memory for one sort or hash before it spills to temp files | It applies per operation, per session, so it multiplies quickly. |
maintenance_work_mem | Memory for VACUUM, CREATE INDEX and similar jobs | Safe to set higher, since few of these run at once. |
effective_cache_size | Nothing is allocated. It tells the planner how much the OS is likely caching. | Too low and the planner shies away from index scans. |
The work_mem row is the one that bites. A setting of 64MB sounds modest. But one complex query might run four sorts, and 200 sessions might run it at once. That's up to 50GB from a single setting.
You can check and change these from psql:
SHOW shared_buffers;
SHOW work_mem;

SET work_mem = '64MB';                          -- this session only
ALTER SYSTEM SET shared_buffers = '2GB';        -- written to postgresql.auto.conf; needs a restart
Why the restart? shared_buffers is one block of memory sized when the server starts, and it can't grow while processes are using it. work_mem is only a limit each backend checks while running a query, so a session can change it any time.
What happens when you run an UPDATE: write-ahead logging
Here's the whole architecture working together. You run an UPDATE in psql and press Enter.
- Your backend receives the SQL text.
- It parses it, applies any view rules, and the planner picks a plan using table statistics.
- The executor looks for the needed pages in
shared_buffers. If they aren't there, it reads them from the table's file. - It changes the row in memory and writes a small record of the change to the WAL buffer.
- When you commit, the WAL up to your commit record is flushed to
pg_wal/on disk. Only then does psql say COMMIT. - Later, the background writer or checkpointer writes the changed page itself back to the table's file.
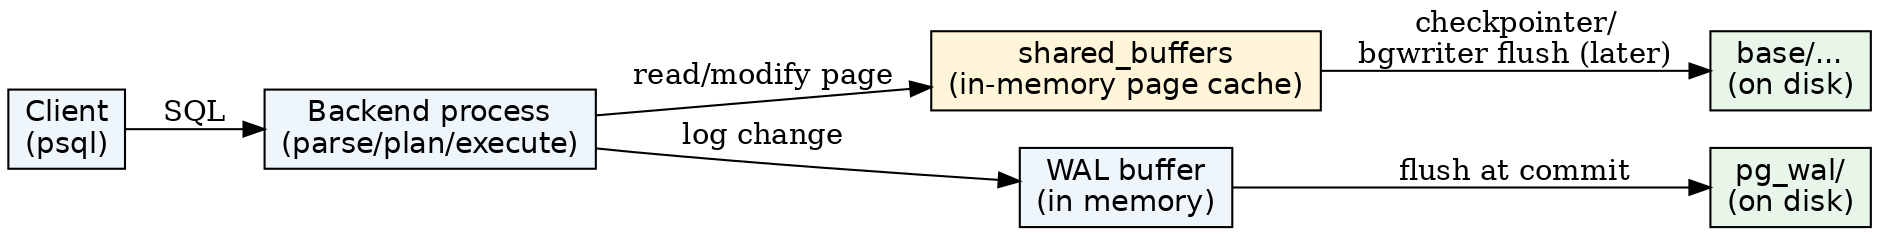
Step 6 surprises people. Your committed change may sit only in memory and in the WAL for minutes. That's safe, because after a crash PostgreSQL replays the WAL and rebuilds the change. This "log first, data later" design is called write-ahead logging. It keeps commits fast, because appending to one log file is much cheaper than rewriting pages scattered across many table files.
Inside the PostgreSQL data directory
Everything above ends up in the data directory you created on Day 1. Find it and list it:
SHOW data_directory;The parts you'll hear about most:
base/has one folder per database, named by its internal ID (OID). Each table and index is a file inside it.global/holds cluster-wide catalogs, such as the list of databases.pg_wal/holds the write-ahead log, in 16MB segment files by default.pg_xact/records whether each transaction committed or aborted.
Data files are made of 8KB pages, the unit PostgreSQL reads and writes. Once a table passes 1GB, it continues in a second file, then a third. Try finding a real table on disk:
CREATE TABLE demo_arch (id int);
SELECT pg_relation_filepath('demo_arch');   -- e.g. base/16384/16390
SELECT oid, datname FROM pg_database;       -- 16384 is your database's folder
Look, but never edit or delete files in base/ or pg_wal/ by hand. Deleting "old" WAL files to free disk space is a classic way to lose a database. Use SQL and the supported tools instead.
Check yourself
work_mem is allowed per sort or hash, per session, so heavy reports running in many sessions can use many multiples of 256MB at once. Lower the global value and raise it with SET only in the sessions that need it.
Those files may hold committed changes that haven't reached the table files yet, and crash recovery needs them. Find out why WAL is piling up instead, such as a failing archiver or a stuck replication slot.
shared_buffers is shared memory allocated once when the server starts, so a reload can't resize it. ALTER SYSTEM wrote the new value to postgresql.auto.conf, and it takes effect after a restart. You can see it waiting with SELECT name, pending_restart FROM pg_settings WHERE name = 'shared_buffers';.
So committed work survives a crash. Writing a small, sequential log record and flushing it to disk is fast, while table pages are written later in the background. After a crash, PostgreSQL replays the WAL from the last checkpoint to rebuild any changes that never reached the data files.
PostgreSQL starts a separate operating system process for every connection, which costs time and memory. Opening hundreds of connections a second wastes resources on setup alone. Use a connection pool, either in the application or with PgBouncer, so a small number of connections serve many requests.