PostgreSQL Data Types Explained
On this page
Choosing PostgreSQL data types
Picking a type takes seconds. Changing it later can mean rewriting a table with a billion rows while the application waits. A good type also catches bad data for free: a date column rejects "next Tuesday", and a text column accepts anything.
The rule that works: pick the type that matches what the value means, not the smallest one that fits today. Here are the decisions you'll make most often.
integer, bigint and numeric for money
| Type | Size | Use it for |
|---|---|---|
integer | 4 bytes, up to about 2.1 billion | Most counts and IDs. The default. |
bigint | 8 bytes, up to about 9.2 quintillion | IDs on tables that could pass 2 billion rows, event counters |
smallint | 2 bytes, up to 32,767 | Rarely worth it. The saving is tiny. |
numeric(p, s) | Varies | Money and anything that must add up exactly |
real, double precision | 4 and 8 bytes | Measurements and science, where tiny rounding is fine |
The money row is the one that matters. Floating-point types store binary fractions, and most decimal fractions, like 0.1, can't be stored exactly. Try it:
SELECT 0.1::double precision + 0.2::double precision;   -- 0.30000000000000004
SELECT 0.1::numeric + 0.2::numeric;                     -- 0.3
Those tiny errors add up across thousands of invoice lines. Use numeric for money, always.
For auto-numbered primary keys you'll see SERIAL in older tutorials. It isn't a real type. It's shorthand for an integer column plus a sequence. New code should use identity columns, which are part of the SQL standard:
CREATE TABLE products (
  id          bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  sku         text NOT NULL,
  price       numeric(10,2) NOT NULL,
  weight_kg   real,
  view_count  bigint NOT NULL DEFAULT 0
);
GENERATED ALWAYS also stops code from inserting its own id by accident. Day 20 compares the two in detail.
text vs varchar vs char
PostgreSQL has char(n), varchar(n) and text. Unlike some databases, they're all stored the same way and perform the same. So the choice is only about rules:
texthas no length limit. Use it by default.varchar(n)rejects anything longer than n characters. Use it when a limit is a real business rule.char(n)pads short values with spaces. That surprises people when they compare or concatenate values, so avoid it.
If you need a limit you might change later, text plus a CHECK constraint is easier to adjust. Day 5 shows how.
timestamp vs timestamptz
There are five time types: date, time, timestamp, timestamptz and interval. The one decision that causes real bugs is timestamp versus timestamptz.
The names mislead. timestamptz doesn't store a time zone. It stores one exact moment, kept in UTC, and shows it in whatever zone your session uses. Plain timestamp stores the wall-clock digits you gave it and has no idea which zone they belong to.
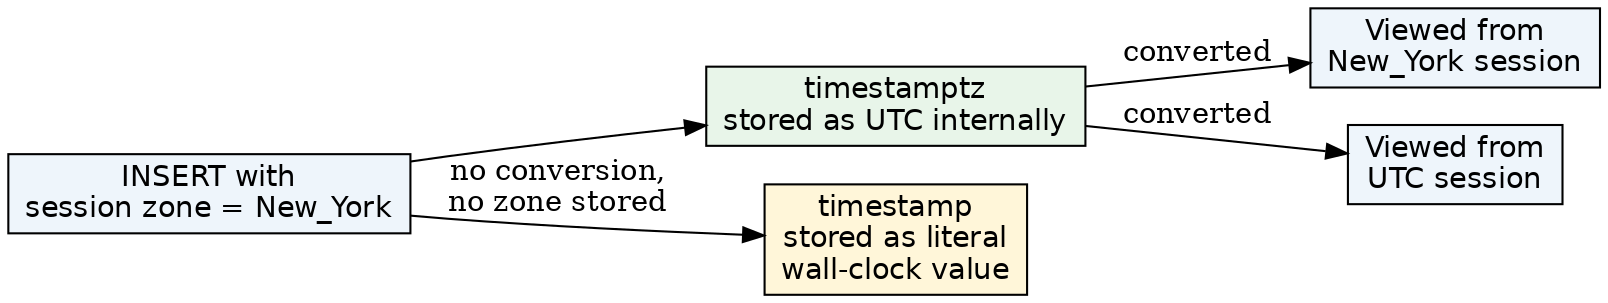
See it for yourself:
CREATE TABLE events (
  id          int GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  is_public   boolean NOT NULL DEFAULT true,
  starts_on   date NOT NULL,
  duration    interval NOT NULL DEFAULT '1 hour',
  created_at  timestamptz NOT NULL DEFAULT now()
);
INSERT INTO events (starts_on) VALUES ('2026-11-02');

SET TIME ZONE 'America/New_York';
SELECT created_at FROM events;
SET TIME ZONE 'Asia/Tokyo';
SELECT created_at FROM events;   -- same moment, different clock
So:
- Use
timestamptzfor anything that happened at a real moment: orders placed, logins, messages sent. - Use
timestamponly for times with no zone, like "the shop opens at 09:00 local time". - Use
datewhen there's no time of day, such as a birthday.
UUIDs, arrays and enums
These three solve specific problems. Each has a catch.
UUID is a 128-bit identifier that any system can generate without asking the database for the next number. That's useful when mobile apps or several services create records offline. gen_random_uuid() has been built in since PostgreSQL 13. PostgreSQL 18 adds uuidv7(), which starts with a timestamp, so new values arrive roughly in order. That keeps indexes compact.
CREATE TABLE sessions (
  id          uuid PRIMARY KEY DEFAULT uuidv7(),
  user_agent  text
);
The catch: a UUID is 16 bytes against 8 for a bigint, and random v4 UUIDs scatter inserts across the whole index.
Arrays hold a list in one column. Any type can be an array:
CREATE TABLE articles (
  id     int GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  title  text NOT NULL,
  tags   text[] NOT NULL DEFAULT '{}'
);
INSERT INTO articles (title, tags) VALUES ('Intro to SQL', ARRAY['sql', 'beginner']);
SELECT title FROM articles WHERE tags @> ARRAY['beginner'];   -- @> means "contains"
The catch: once you need to join on the items, count them across rows or attach details to each one, a separate table works better.
ENUM limits a column to a fixed list of labels, and the database enforces it:
CREATE TYPE order_status AS ENUM ('pending', 'paid', 'shipped', 'cancelled');
CREATE TABLE orders (
  id      int GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  status  order_status NOT NULL DEFAULT 'pending'
);
ALTER TYPE order_status ADD VALUE 'refunded';
The catch: you can add a label and rename one, but you can't remove one. If the list changes often or each value needs extra details, use a lookup table instead.
JSON: default to jsonb
There are two JSON types. json stores the text exactly as you sent it. jsonb parses it into a binary format, which is a little slower to write and much faster to query, and it can be indexed. Use jsonb unless you must keep the original formatting or key order.
SELECT '{"theme": "dark", "beta": true}'::jsonb ->> 'theme'; -- dark-> returns a JSON value and ->> returns text. Day 18 goes much deeper.
Check yourself
Floating point can't store most decimal fractions exactly, so small rounding errors build up as lines are added. Store money as numeric with a fixed scale, such as numeric(12,2).
Each server wrote its own local wall-clock time with no zone attached, so the same digits mean different moments. Use timestamptz, which stores one exact moment and converts it for each session.
PostgreSQL can add or rename ENUM labels but can't remove one. You'd need a new type and a migration of every column using it, which is why changing lists belong in a lookup table.
Usually not in PostgreSQL. text and varchar are stored the same way and perform the same, and the 255 limit is a habit from other databases with no real meaning here. Use text, and add a CHECK (length(name) <= 200) only if the business has an actual limit.
For data whose shape varies or that you mostly store and return as a whole, such as third-party webhook payloads or optional per-product attributes. Use normal columns for fields you filter, join or constrain often, because columns get type checks, constraints and simpler indexes. A mix is common.