Database Normalization with PostgreSQL Examples
On this page
Update, insert and delete anomalies
Most bad schemas start as a spreadsheet. One row per order, with everything you might want to know crammed into it:
| order_id | customer_email | customer_name | products | ship_zip | ship_city |
|---|---|---|---|---|---|
| 1 | ana@example.com | Ana Silva | SKU-100:2, SKU-204:1 | 10001 | New York |
| 2 | ana@example.com | Ana Silva | SKU-204:3 | 10001 | New York |
| 3 | ben@example.com | Ben Ortiz | SKU-317:1 | 94105 | San Francisco |
It works until it doesn't. Three kinds of problem show up, and they have names:
- Update anomaly. Ana changes her name. You must update every one of her orders, and if you miss one, the data contradicts itself.
- Insert anomaly. You can't record a new customer until they place an order, because there's nowhere else to put them.
- Delete anomaly. Delete Ben's only order and you lose the fact that Ben exists.
Normalization is a set of rules that removes these problems. The idea behind all of them: each fact is stored in exactly one place. The rules are numbered as normal forms, and each one fixes one kind of duplication. Here's the table cleaned up one form at a time.
First normal form: one value per cell
The products column holds a list packed into text. You can't ask "how many units of SKU-204 did we sell?" without parsing strings. First normal form (1NF) says every column holds a single value, with no lists and no repeating groups.
The fix is a child table with one row per product per order:
CREATE TABLE order_items (
  order_id  int  NOT NULL,
  sku       text NOT NULL,
  quantity  int  NOT NULL CHECK (quantity > 0),
  PRIMARY KEY (order_id, sku)
);
Now the sales question is a simple sum(quantity) ... WHERE sku = 'SKU-204'.
PostgreSQL arrays (Day 4) look like they break this rule. For a small list of labels with no details of their own, such as tags on a post, an array is a reasonable, deliberate choice. If the items have their own attributes, like products with names and prices, give them a table.
Second normal form: depend on the whole key
Say you add the product name and price to order_items:
CREATE TABLE order_items_v2 (
  order_id      int,
  sku           text,
  quantity      int,
  product_name  text,           -- depends on sku alone
  PRIMARY KEY (order_id, sku)
);
The key is (order_id, sku), but product_name only depends on sku. Every order for the same product repeats its name. That's a partial dependency, and second normal form (2NF) forbids it. It only applies to tables with a composite key. Move product facts into a products table and reference it by sku.
There's an important exception, and it's where design judgment beats mechanical rules. Keep unit_price on order_items. It's the price at the time of sale, a fact about that order line. The product's current price lives in products. They look like the same thing, but they're different facts.
Third normal form: no facts about other facts
The original table also has ship_zip and ship_city. The city depends on the zip code, and the zip depends on the order. So the city depends on the order only through another non-key column. That's a transitive dependency, and third normal form (3NF) forbids it. If you need to fix a misspelled city, you'd have to change every order shipped there.
The textbook fix is a zip_codes table keyed by zip. In practice many teams keep the full address on the order anyway, as a snapshot of where it was shipped. That's fine when you've decided it on purpose.
There's a well-known way to remember the three forms: every non-key column must depend on the key (1NF), the whole key (2NF) and nothing but the key (3NF). There's also a stricter Boyce-Codd normal form (BCNF) for rare cases with overlapping candidate keys. Aim for 3NF and you'll rarely hit them.
The normalized e-commerce schema
Putting it together for a small shop:
DROP TABLE IF EXISTS order_items, order_items_v2;   -- clear the sketches above

CREATE TABLE customers (
  customer_id  int GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  email        text NOT NULL UNIQUE,
  full_name    text NOT NULL
);
CREATE TABLE categories (
  category_id  int GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  name         text NOT NULL UNIQUE
);
CREATE TABLE products (
  sku          text PRIMARY KEY,
  category_id  int NOT NULL REFERENCES categories,
  name         text NOT NULL,
  list_price   numeric(10,2) NOT NULL CHECK (list_price >= 0)
);
CREATE TABLE orders (
  order_id     int GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  customer_id  int NOT NULL REFERENCES customers,
  status       text NOT NULL DEFAULT 'pending',
  created_at   timestamptz NOT NULL DEFAULT now()
);
CREATE TABLE order_items (
  order_id     int NOT NULL REFERENCES orders,
  sku          text NOT NULL REFERENCES products,
  quantity     int NOT NULL CHECK (quantity > 0),
  unit_price   numeric(10,2) NOT NULL,
  PRIMARY KEY (order_id, sku)
);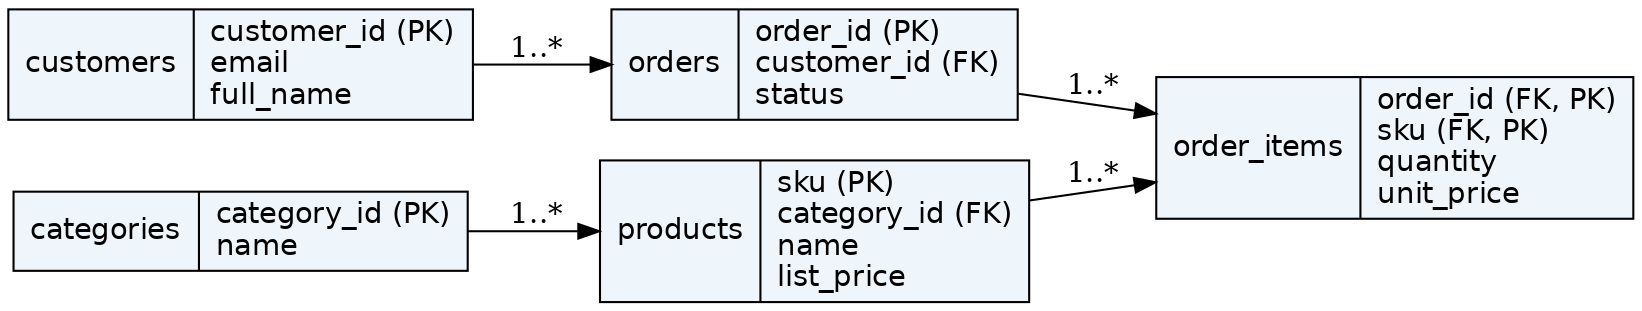
Two design choices are worth noticing. Orders and products have a many-to-many relationship: an order has many products, and a product appears in many orders. Relational tables always model that with a junction table, here order_items. And customers use a generated id as the primary key, while email stays UNIQUE. Emails change, and you don't want every order to need updating when one does.
When to denormalize
Normalization protects writes. Reads sometimes pay for it with joins. Denormalizing means adding redundancy back on purpose to speed up a known, measured read. Common, sensible cases:
- An
order_totalcolumn on orders, instead of summing order_items on every page view. - A customer name snapshot on invoices, so an old invoice never changes.
- A summary table or materialized view (Day 10) for dashboards.
Do it in that order: normalize, measure with EXPLAIN ANALYZE (Day 22) on realistic data, then denormalize only what's slow. Often an index on the foreign key column solves the "slow join" without any redundancy. When you do denormalize, write down which column is the source of truth and what keeps the copy in sync, whether that's a trigger, a job or application code.
Check yourself
Third normal form: the email depends on the teacher, not on the course. Move teachers into their own table and reference them with teacher_id.
They're different facts. unit_price records what the customer paid at the time of sale, which must not change when the list price does.
Measure the query with EXPLAIN ANALYZE on realistic data, and check that orders.customer_id is indexed. Denormalize only if the join is still the bottleneck after that.
First normal form, which requires one value per cell. Finding all products tagged sale needs string matching, renaming a tag means rewriting text in many rows, and you can't enforce valid tags with a foreign key. Use a separate product_tags table, or an array column if you accept its trade-offs.
A column depends on another non-key column rather than on the key. For example, orders storing both zip_code and city means city depends on zip code, so the same fact is repeated in many rows and can contradict itself. Move it to a table keyed by the column it really depends on.