Elasticsearch Pagination: From/Size vs search_after
On this page
The 10,000 result window limit
Page 500 of a product listing: from: 9995, size: 10. Elasticsearch refuses:
Result window is too large, from + size must be less than or equal to: [10000] but was [10005].
See the scroll api for a more efficient way to request large data sets.
The limit exists for a reason.
Why deep from/size pagination is expensive
To return results 9,995 to 10,005, every shard must find its own top 10,005 documents, send them to the coordinating node, which sorts all of them (10,005 × number of shards) and throws away all but ten. Cost grows with depth on every page. The index.max_result_window setting (default 10,000) protects the cluster; raising it just moves the problem.
For user-facing search, that's usually fine: people rarely go past page 10. Cap the page number in the UI, and offer filters instead of page 500.
Deep pagination with search_after and a point in time
For deep or complete traversal (exports, infinite scroll, sync jobs), continue after the last result's sort values, like cursor pagination in APIs.
1. Open a point in time (PIT) so all pages see the same snapshot of the index, unaffected by new writes:
POST /products/_pit?keep_alive=2m2. First page, sorted by price with a tiebreaker:
POST /_search
{
  "size": 4,
  "query": { "term": { "in_stock": true } },
  "pit": { "id": "<pit id>", "keep_alive": "2m" },
  "sort": [ { "price": "desc" }, { "_shard_doc": "asc" } ]
}page 1: [('Budget Laptop', [399.0, 11]), ('Standing Desk', [349.0, 20]),
('Chromebook 14', [279.0, 17]), ('Office Chair', [229.0, 23])]3. Next page: pass the last hit's sort values as search_after:
"search_after": [229.0, 23]page 2: [('Wireless Earbuds', [129.0, 35]), ('Bluetooth Speaker', [79.0, 32]),
('Gaming Mouse', [59.99, 8]), ('Wireless Keyboard', [49.99, 5])]4. Close the PIT when done (DELETE /_pit with the id): {"succeeded":true,"num_freed":1}.
_shard_doc is a built-in, efficient tiebreaker that's unique within a PIT; without a unique tiebreaker, documents with equal prices could be skipped or repeated. Each page costs the same, however deep.
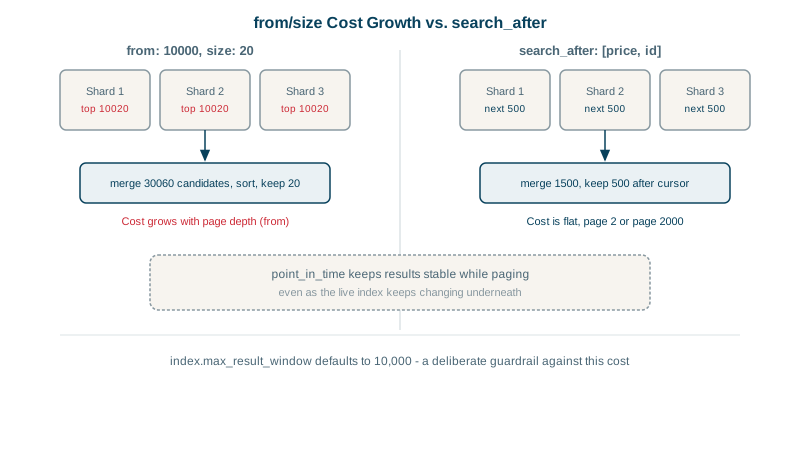
from/size vs search_after vs scroll: which to use
| Need | Use |
|---|---|
| Search results pages, shallow | from / size, capped at a few hundred results |
| Infinite scroll, "load more" | search_after (a PIT if consistency across pages matters) |
| Export or reindex everything | PIT + search_after, or the reindex API for copies |
| Old scroll API | Still works, but PIT + search_after is the recommended replacement |
Track total cheaply: by default the total count is accurate up to 10,000 ("relation": "gte" beyond); set track_total_hits only when you need exact counts.
Check yourself
Every shard must gather all results up to that depth and the coordinator sorts and discards them, so work grows with the page number.
It's a unique tiebreaker available with a point in time. Without one, documents with equal primary sort values, like the same timestamp, could be skipped or repeated between pages.
A consistent snapshot of the index, so pages don't shift as documents are added, changed or deleted during the traversal. Close it when finished to free resources.
Elastic now recommends search_after with a point in time for deep pagination and exports. Scroll still works but holds more resources.
Users rarely go that deep, and deep pages are expensive. Better filters and "load more" with search_after serve users better.