Kafka Broker Failures and Under-Replicated Partitions
On this page
What happens when a Kafka broker dies
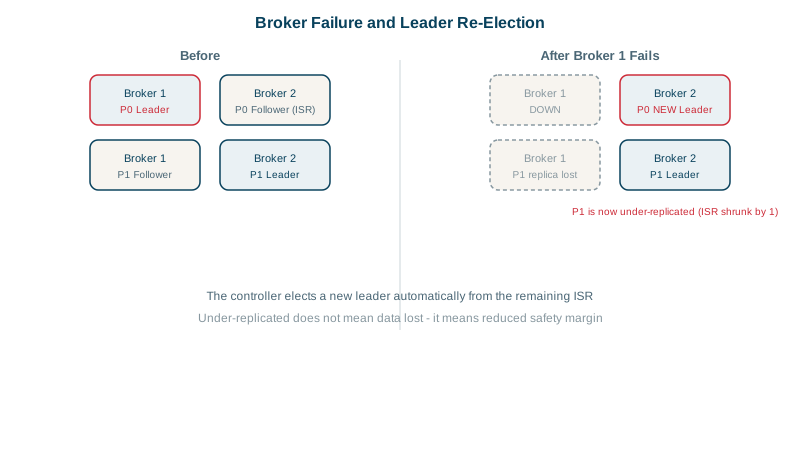
Broker 3 in a five-broker cluster loses power. With replication factor 3 and min.insync.replicas=2 (Day 9):
- The controller notices broker 3 has stopped heartbeating (seconds, set by
broker.session.timeout.ms). - For every partition broker 3 led, the controller picks a new leader from that partition's ISR and updates the metadata.
- Producers and consumers get errors such as
NOT_LEADER_OR_FOLLOWER, refresh metadata, and continue with the new leaders. With retries and idempotence on (Day 5), producers don't lose or duplicate records. - Partitions where broker 3 was a follower keep their leaders but now have only two in-sync replicas: they're under-replicated, but still accept writes because 2 meets the minimum.
The cluster keeps working. Nothing is lost. But the safety margin is gone for those partitions: one more failure among their replicas and writes stop.
Finding under-replicated and offline partitions
bin/kafka-topics.sh --bootstrap-server kafka1:9092 --describe --under-replicated-partitions
bin/kafka-topics.sh --bootstrap-server kafka1:9092 --describe --under-min-isr-partitions
bin/kafka-topics.sh --bootstrap-server kafka1:9092 --describe --unavailable-partitionsTopic: orders Partition: 4 Leader: 1 Replicas: 1,3,5 Isr: 1,5
Topic: orders Partition: 9 Leader: 5 Replicas: 3,5,2 Isr: 5,2Broker 3 is missing from every ISR it should be in: that confirms which broker the problem is.
When the broker comes back
The returning broker's replicas aren't in sync yet. Each fetches everything it missed from the current leaders and rejoins the ISR once caught up. That can take minutes to hours for a broker that held a lot of data (tiered storage, Day 22, shortens it). Leadership doesn't automatically jump back immediately; with auto.leader.rebalance.enable=true (the default), the controller periodically moves leadership back to each partition's preferred leader so load evens out again.
Broker failure runbook
Under-replicated partitions, one broker absent from many ISRs:
- Check that broker: process up? disk full or failing? network? JVM pauses in the logs?
- If it's down, restart it and watch URP fall as it catches up.
- If the hardware is gone, replace the broker with the same broker id and empty storage; it re-replicates its partitions from leaders.
Under-replicated partitions spread across many brokers:
- Usually overload, not failure: disks or network saturated, followers can't keep up. Check throughput, request handler idle ratio, and recent partition reassignments that may be copying data.
Under-min-ISR or offline partitions:
- Writes (or everything) are failing for those partitions. Restore a replica's broker first. Unclean leader election (Day 9) brings an offline partition back at the cost of data loss; use it only with a deliberate decision.
Moving data off a broker (decommissioning, rebalancing): use kafka-reassign-partitions.sh with a generated plan and a throttle (--throttle) so replication traffic doesn't starve clients, or a tool such as Cruise Control.
Practice broker failures in staging
Kill a broker in a staging cluster under realistic load and watch: how long until clients recover, how long URP lasts, whether any producer errors reach users. Do it before production does it for you (System Design Roadmap, Day 79).
Check yourself
Yes. For partitions the failed broker led, the controller elects new leaders from the remaining in-sync replicas. Every partition still has two in-sync copies, which meets min.insync.replicas=2, so acks=all writes keep succeeding. A second failure would block writes to affected partitions.
Overload rather than failure: followers can't replicate fast enough because disks, network or request handler threads are saturated, or a large partition reassignment is consuming bandwidth. Check broker resource metrics and any reassignment in progress.
Start a new broker with the same broker id and empty storage; it re-replicates its partitions from the current leaders and rejoins the ISRs.
It rejoins, its replicas catch up from the current leaders, and once in sync they rejoin the ISR. Leadership then moves back gradually through preferred leader election, which balances load again.